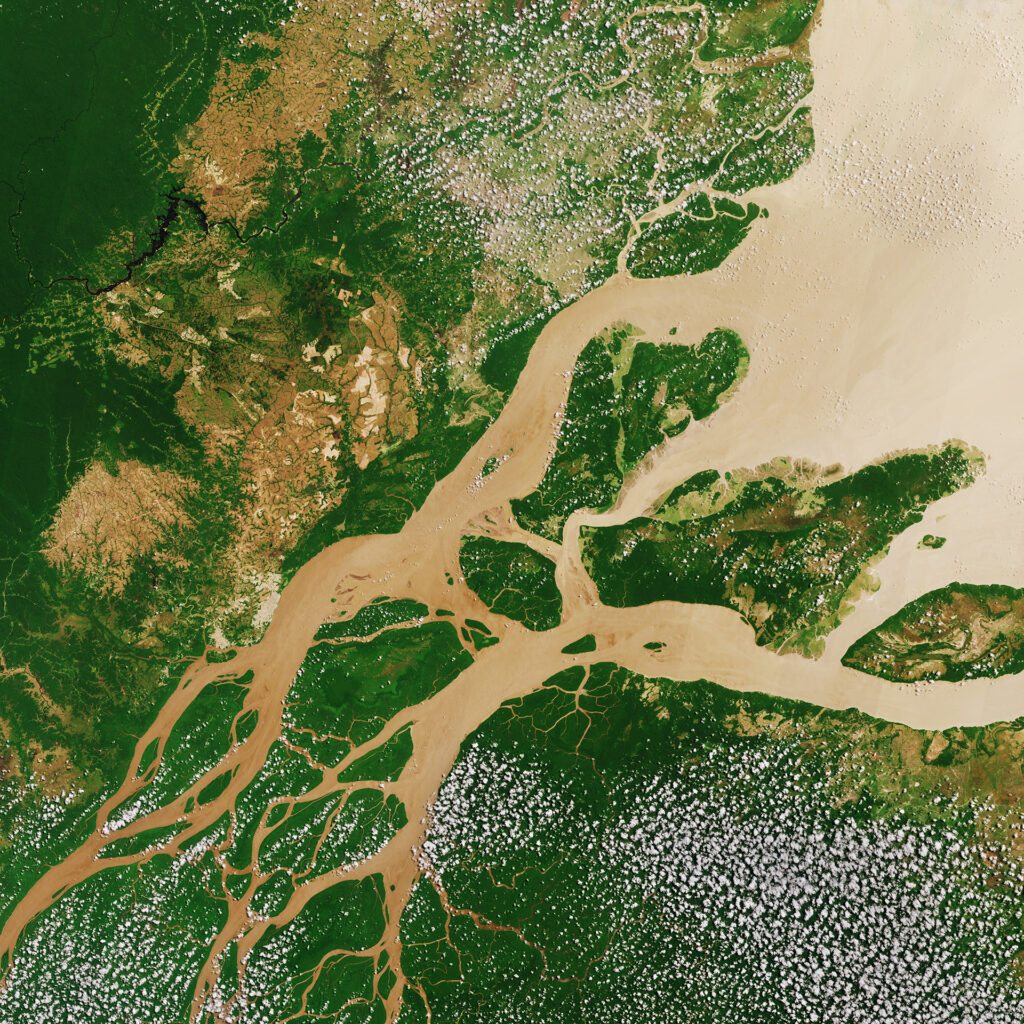
Behind almost every supervised model that reads satellite imagery sits a small set of images that someone examined closely and labelled by hand. Usually there are a few hundred of them, sometimes a couple of thousand. That handful is the whole of what the model knows. From it, the model learns to tell flooded farmland from merely saturated farmland, and a sound roof from a failing one.
That small labelled set is tiny next to the volume of imagery that actually exists. Satellites photograph the planet on a fixed schedule, so images pile up constantly, whether or not anyone needs them, and most are never used. Labelling them is the slow part. It takes a trained specialist to say what a given pixel actually shows, and even a specialist gets through only a few scenes a day.
This leaves two separate shortages. The first is a shortage of labels. Images are plentiful, but very few have been checked and labelled, so we rarely know for certain what any given one shows. The second is a shortage in the archive itself. It contains only what actually happened, recorded at the moments a satellite passed overhead. If you need a scene that never occurred, or one that no satellite happened to capture, the archive does not hold it.
Synthetic satellite data helps with both shortages, in seven distinct ways. Each one lets a team attempt work that a small labelled dataset would otherwise rule out.
A model reading a satellite scene has to learn several properties of the scene at once: the shapes of the objects in it, the textures that distinguish one surface from another, the spatial context that makes the scene plausible, and the radiometric response of the sensor that recorded it. Generated scenes can carry the first three in any quantity, as much as a training schedule asks for.
The usual approach is to pretrain on generated data and then fine-tune on the real examples, so each source does what it does best. The generated data teaches structure. The real data ties the model to the specific sensor and place. The real dataset no longer sets the ceiling on what the task can attempt, so a project that once looked like a two-year annotation effort becomes a generation run plus fine-tuning on the images you already have.
Many of the most valuable predictions concern rare events, such as a dam under stress, a once-in-a-century flood, or vegetation growing into a power line until it trips. Each of these shows up in the archive only a handful of times, scattered across different regions, seasons and sensors. A model trained on that record learns everyday conditions in fine detail and barely sees the rare ones.
With generated data, you decide how often the rare event appears. You can produce that class deliberately, in all the forms it takes, and at whatever share of the training set gives the model a fair chance of learning it. How often it appears becomes something you control, not something the archive dictates.
Most of the time and money goes into hand annotation, and the cost climbs with the precision a task demands. Marking where water sits in a flood scene is laborious enough. Tracing the exact edge of every roof plane, or the species boundary in a mixed stand, is harder still, and the result is subjective, because it depends on how the annotator read the scene.
A generated scene already knows its own contents. Whoever built it set the shapes, the surface materials, the water extent and the position of every object, so the labels exist before the image does and match it exactly. That gives you pixel-level masks for tasks where hand annotation would be impractical. It even captures attributes no annotator could read off an image at all, such as soil moisture or the true height of a building.
Some of the most useful training data comes in matched pairs, and real observation can only ever give you one half of each. Teaching a model to see through cloud means showing it the same place at the same moment, both clouded and clear. A change detector needs a before and an after that differ in just one respect. To evaluate a super-resolution method, you want the same scene at two resolutions and nothing else changed.
A generator produces both halves directly: it renders the same scene twice and changes only the one variable you care about. No other method matches this, and it makes matched-pair tasks such as cloud removal, change detection and super-resolution practical even where no real archive could supply the pairs.
Labelled Earth observation data clusters where the funding is. Careful annotation exists in quantity for parts of North America and Europe, and only thinly across much of the tropics and the global south. A model trained on that record inherits the imbalance. It has learned what a field, a roof or a road looks like mainly in the places that paid for labels first.
You can generate scenes that match the biome, buildings, crop calendar and atmosphere of wherever the model will actually run. Coverage becomes a matter of choosing what to generate. That matters most in exactly the places where labelled data is scarcest and the environmental stakes are highest.
Generated data is mostly used to train models. It is just as useful for testing them, and that side is often overlooked. A held-out set of real images tells you how a model does on the conditions that happened to be in your sample. A generated test set tells you how it does on the specific conditions you choose to test.
That matters most when a model feeds a decision with money or safety attached. When you sweep haze, sun angle, season, terrain steepness and sensor noise across a controlled range, you get a map of where accuracy holds and where it starts to slip. A validation report can carry that map, and a reviewer or a regulator can act on it.
High-resolution imagery comes with licence terms, and they usually restrict redistribution. Teams working across organisations often find themselves unable to share the dataset behind a result, which slows collaboration and makes independent reproduction difficult.
Generated scenes carry no such restriction. A benchmark built on synthetic data can be published in full, a partner can run the same evaluation on the same inputs, and a supplier can demonstrate a method on data the client is free to keep and reuse. In consortium research and in regulated settings, being able to hand over the actual data is often what makes a collaboration or an audit possible at all.
Across these seven uses, one thread runs through all of them. The amount of hand-labelled imagery a team can gather no longer sets the limit on what a model can learn. Generated data fills a small dataset out to a usable size, supplies the rare events a real archive barely contains, arrives with exact labels already attached, produces the matched pairs that reality cannot, covers the regions where real labels are thin, gives a controlled way to test a finished model, and can be shared without licence restrictions.
The direction of travel is for generated data to become a standard part of the training pipeline. The combination of pretraining on generated scenes and fine-tuning on real ones is increasingly common, and as the generated data improves, the balance a task needs shifts further towards it. For anyone building on satellite data, the practical result is that the tasks once shelved for lack of examples are the first ones to revisit.
Another Earth generates high-resolution synthetic Earth observation data, designed to train and test the AI models used across environmental, infrastructure and climate work. Our aim is to help organisations move from reacting to what has already happened towards anticipating what comes next, by building the predictive data layer for the physical world.